The heavier design
The lighter lookup only helps where a library’s authors wrote a skill. Most libraries have not. The codex is the answer for the rest: read the documentation every library already ships in its own source, rewrite each piece into one plain sentence with a local model so the original never reaches an agent, and search the result by meaning. Two things decide its shape: what it costs, and what the agent is allowed to read — and two of its choices carried over to the lighter lookup, one store per machine and answers scoped to the project.
The cost problem, and why the store is shared
Section titled “The cost problem, and why the store is shared”The expensive step is rewriting each piece of documentation into a sentence in a caller’s own words, and that is one local model call per documented declaration. A single small project — 99 dependencies — produces about 5,400 of them once duplicates are removed. Rebuilding that for every project, on every machine, in front of every checkout, is not a thing anyone would run twice.
But a resolved dependency never changes. io.ktor:ktor-client-core:3.5.1 is the same artifact
everywhere, for ever, so what we extract from it is the same too. That makes it cacheable with no
invalidation problem at all — the same property the Gradle and Maven caches already rely on.
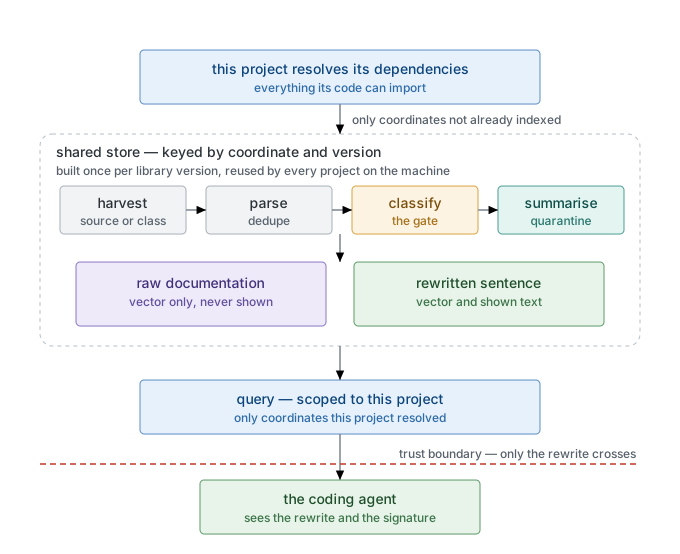
So the store lives on the machine, not in the project, keyed by coordinate and version. The first project to use a library pays. Every project after that pays nothing. Without this the design does not work, and the rewriting step — which is also the security control — would have to be dropped.
The per-project part is small, and it is a boundary
Section titled “The per-project part is small, and it is a boundary”A project resolves its dependencies and writes down what it resolved. That is the entire build-time cost: no database is opened, nothing is indexed, and nothing is fetched. A small service on the machine does the rest — it works out which of those coordinates it has never seen, and indexes only those. Everything else is already there. The build stays out of it deliberately: a store opened from the build would put a database on every consuming project’s build classpath, and make every build daemon on the machine a writer to a single file.
Queries are then scoped to the coordinates that project actually resolved. This is not a performance filter. A shared store holds entries from every library any project on the machine has ever pulled in, and without the scope a poisoned entry dragged in by one project would be reachable from another that never depended on it — a laundering route created by our own caching decision. The scope is what closes it.
By default the index covers everything the project’s code can import — what it declares, and what those libraries expose to it — not only the declared dependencies. That was a measured choice: 11 of 17 capabilities a developer actually reached for lived only in that tail.
Two faces, because they fail on different questions
Section titled “Two faces, because they fail on different questions”Each entry is stored twice over: once as the library’s own documentation, and once as the rewritten sentence. Both are searchable; only the rewrite is ever displayed.
That is safe because a search key is a list of numbers, and nothing reads it. The original text can decide which entry surfaces without ever reaching the agent — which also means an entry whose rewrite was rejected can still be found, rather than silently vanishing from search.
Keeping both is measurably better than either alone: on the same questions, both faces together put the right answer in the first ten 15 times out of 17, against 13 for the documentation alone and 10 for the rewrite alone. Gluing the two texts into a single key is worse than either — the gain needs them kept apart.
The boundary at the bottom
Section titled “The boundary at the bottom”Library documentation is written by whoever published the library, and some of it is hostile. The rewriting step exists so that text never reaches the agent verbatim, and a cheap classifier sits in front of it to catch the casual attempts before they get that far.
What crosses the line to the agent is the rewrite and the signature. Nothing else does.
The decision behind all of this, including what was rejected, is ADR-0012.
Text on this site is licensedCC BY 4.0; source code underApache 2.0. © 2026 Brill Pappin.